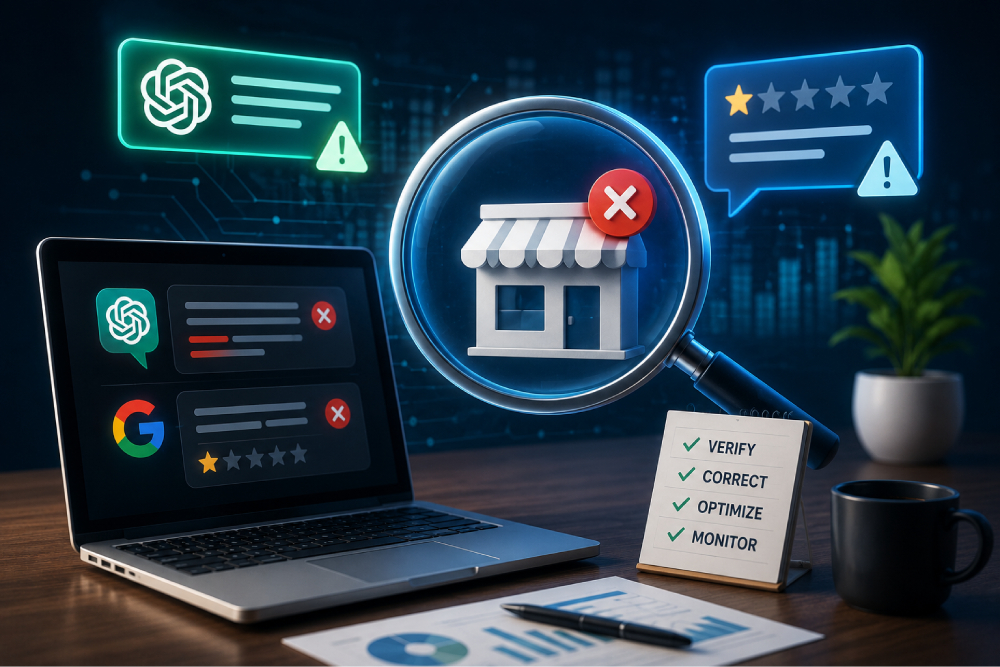
A prospect asks ChatGPT what a business does, what it costs, and whether it is worth trying. The answer sounds confident and specific. It is also wrong, and the business only finds out weeks later when a lead repeats the wrong price back to a sales team mid-call.
This is no longer a rare glitch. As more buyers open an AI assistant before they open a search engine, a wrong answer about a business is not a trivia problem, it is a reputation and revenue problem happening silently in the background. This article explains why it happens, how to tell which kind of error is occurring, and the actual sequence that fixes it.
TL;DR
AI assistants get business facts wrong because they build answers from thin, stale, or contradictory information scattered across the web. A simple browsing-on versus browsing-off test reveals whether the error is parametric (stale training data) or a retrieval error (a specific bad source), and the two need different fixes. The reliable correction sequence is capture evidence, find the actual source, fix it, confirm AI crawlers aren’t blocked, force a recrawl, and re-test. Prevention comes down to keeping facts consistent everywhere the business is mentioned, not just on its own site.
Why AI Assistants Get Business Facts Wrong
AI systems build their picture of a business from every signal they can find across the web: the company’s own site, review platforms, old press releases, directories, and cached pages. When those signals disagree with each other, the model has to guess which version is correct, and it does not always guess right.
Three patterns account for most of these errors. Information gaps happen when the model cannot find a confident source for a specific fact, such as current pricing, and fills the gap with a plausible-sounding answer instead of an honest “I don’t know.” Stale sources happen when an outdated directory listing or a cached review page outranks the business’s current site in whatever the model retrieves from. Entity confusion happens when a business shares a name, category, or positioning with a competitor, and the model blends details from both into one answer.
None of these are the model “lying.” A language model predicts likely text based on patterns in what it has read, and when the available signals are thin or contradictory, the most likely text is not always the correct one.
Parametric vs. Retrieval Errors: Why the Fix Is Different
Not every wrong answer comes from the same place, and knowing which one is happening changes the entire fix. Some AI answers come from the model’s training data, frozen at a point in time. Others come from a live retrieval or browsing step that fetches a current page and summarizes it.
This distinction matters because the two fixes run on completely different timelines. A retrieval-layer error can often be corrected within days once the right source is fixed and recrawled. A purely parametric error may not disappear until the model’s next training cycle, if at all, which means the more durable fix is making the live, correct signal so consistent and well-corroborated that retrieval is favored over the model’s outdated default.
The Correction Sequence That Actually Works
Once the type of error is identified, correcting it follows a repeatable sequence rather than a single action.
Start by capturing evidence. Screenshot the full answer along with the exact prompt, the date, and the model name, then re-run the same prompt several times to see how consistently the error appears. This baseline is what proves later whether a fix actually worked, rather than just seeming to.
Next, find the specific source the answer is actually pulling from, not just “the internet” in general. This usually means searching for the exact wrong phrasing to locate the outdated directory listing, cached review, or old press mention the model is drawing from, and correcting that source directly rather than only updating the business’s own website.
Then confirm crawler access. Check that robots.txt is not blocking the AI crawlers that matter, including GPTBot, PerplexityBot, ClaudeBot, and Google-Extended, since a blocked crawler cannot see a correction no matter how accurate it is. Submit the corrected URL through Google Search Console and Bing Webmaster Tools to encourage a faster recrawl.
Finally, use in-product feedback as a supporting signal, not the primary fix. This source-first approach is a core part of effective AI SEO services, helping businesses improve how AI platforms present accurate information. Thumbs-downing a wrong answer and describing the specific false fact can help, but it rarely flips an answer on its own. The source-level correction combined with a confirmed recrawl is what actually moves the needle, which is why many businesses rely on AI SEO services to improve their visibility and accuracy across AI search platforms
Common Error Types and Their Likely Fixes
The table below maps the most common categories of AI errors about a business to their typical cause and the fix that applies.
| Error Type | Likely Cause | Fix |
|---|---|---|
| Outdated pricing | Stale review site or directory cache | Update and recrawl the stale third-party source |
| Discontinued service listed as current | Old page still indexed, not redirected | Redirect or update the legacy page directly |
| Wrong founder or leadership name | Parametric: stale training data | Strengthen live signal consistency; expect training-cycle lag |
| Features attributed to a competitor | Entity confusion between similarly named brands | Sharpen distinctive brand language and category framing |
| “Is this legit?” doubt | Thin citation surface, few trusted sources | Build presence on authoritative third-party sources |
Prevention: Building a Consistent Source of Truth
The businesses that get hallucinated about least are not the ones with the most content. They are the ones whose facts agree with each other everywhere they appear: the same pricing, the same service descriptions, and the same leadership names across the company’s own site, directory listings, review platforms, and any third-party mentions.
A short, canonical one- or two-sentence description of the business, used consistently across the website, directories, and social profiles, gives AI systems a clean, repeatable signal to retrieve instead of forcing them to average across several slightly different versions—a best practice followed in AI search engine optimization services
Auditing the top pages that mention a business, including third-party directories and old press coverage, and fixing or redirecting outdated ones is unglamorous work, but it is a key part of AI search engine optimization services that helps maintain accurate AI-generated business information.
When It Crosses Into Something Legal, Not Just an SEO Problem
Most AI errors about a business are ordinary hallucinations: wrong pricing, an outdated service, a confused competitor detail. These are corrected through the source-level process above, not through legal action.
A smaller number of cases genuinely cross into defamation, such as a fabricated lawsuit, an invented scandal, or a false claim of illegal activity. These deserve documentation and, where appropriate, legal counsel, since courts are still actively working out how liability applies to AI-generated statements and outcomes have varied. Treating legal escalation as a parallel track for genuinely serious cases, rather than a first response to an ordinary factual error, keeps effort focused on the corrections that are actually fixable through the source-level process.
Key Takeaways
- AI systems generate answers about a business from whatever signals they can find across the web, and contradictory or stale signals are the leading cause of factual errors.
- A simple browsing-on versus browsing-off test reveals whether an error is parametric (stale training data) or a retrieval error (a specific bad source), and the two require different fixes.
- The reliable correction sequence is capture evidence, find the actual source, fix it, confirm crawler access, force a recrawl, and re-test.
- In-product feedback like thumbs-down can support a fix but rarely reverses an answer on its own.
- Consistency of facts across a business’s own site, directories, and third-party mentions is the strongest prevention against future hallucinations.
- Genuinely defamatory claims are a legal matter, not an SEO fix, and should be handled as a separate, parallel track.
Frequently Asked Questions
Why does ChatGPT get basic facts about a business wrong?
Most errors come from thin, stale, or contradictory information across the web that the model has to average across. When no confident source exists for a specific fact, the model fills the gap with a plausible-sounding guess instead of stating uncertainty.
Can a business ask OpenAI or Google to correct a specific fact directly?
Not reliably. Neither platform offers a dedicated brand-correction channel for company facts. The practical path is correcting the underlying sources the model retrieves from and confirming the correction gets recrawled, rather than requesting a manual override.
How long does it take for a correction to actually show up in AI answers?
Retrieval-based errors can resolve within days to a couple of weeks once the correct source is fixed and recrawled. Errors baked into the model’s training data may persist until a future training cycle, which is why the retrieval-layer fix matters more in the short term.
Does blocking AI crawlers protect a business from being misquoted?
No. Blocking crawlers like GPTBot only limits future crawling of new content; it does not remove information the model already learned, and it can make corrections harder to surface since the corrected page becomes invisible to the crawler as well.
Is this the same work as traditional SEO?
It overlaps with traditional SEO in crawlability, authority, and content quality, but correcting AI errors also requires entity consistency across third-party sources and ongoing answer-level monitoring, which most traditional SEO retainers do not include by default.
Conclusion
A wrong answer about a business inside ChatGPT or Google’s AI Overviews is not a rare edge case anymore. It is a predictable outcome of thin or contradictory information sitting in the places AI systems already look, and it is fixable through a specific, repeatable process rather than luck or a support ticket.
Working with an AI SEO agency in India that treats AI accuracy monitoring as an ongoing practice, not a one-time cleanup, is the difference between catching a wrong answer before a prospect repeats it back and finding out after a deal has already been lost.
